Headline finding: I audited 17 AI Safety Talent programmes. Zero of 17 have published any comparison group, rejected-applicant follow-up, matched control or randomisation. Not one. Every programme that mentions a counterfactual does it by asking participants to self-report.
Background
At least $70 million...
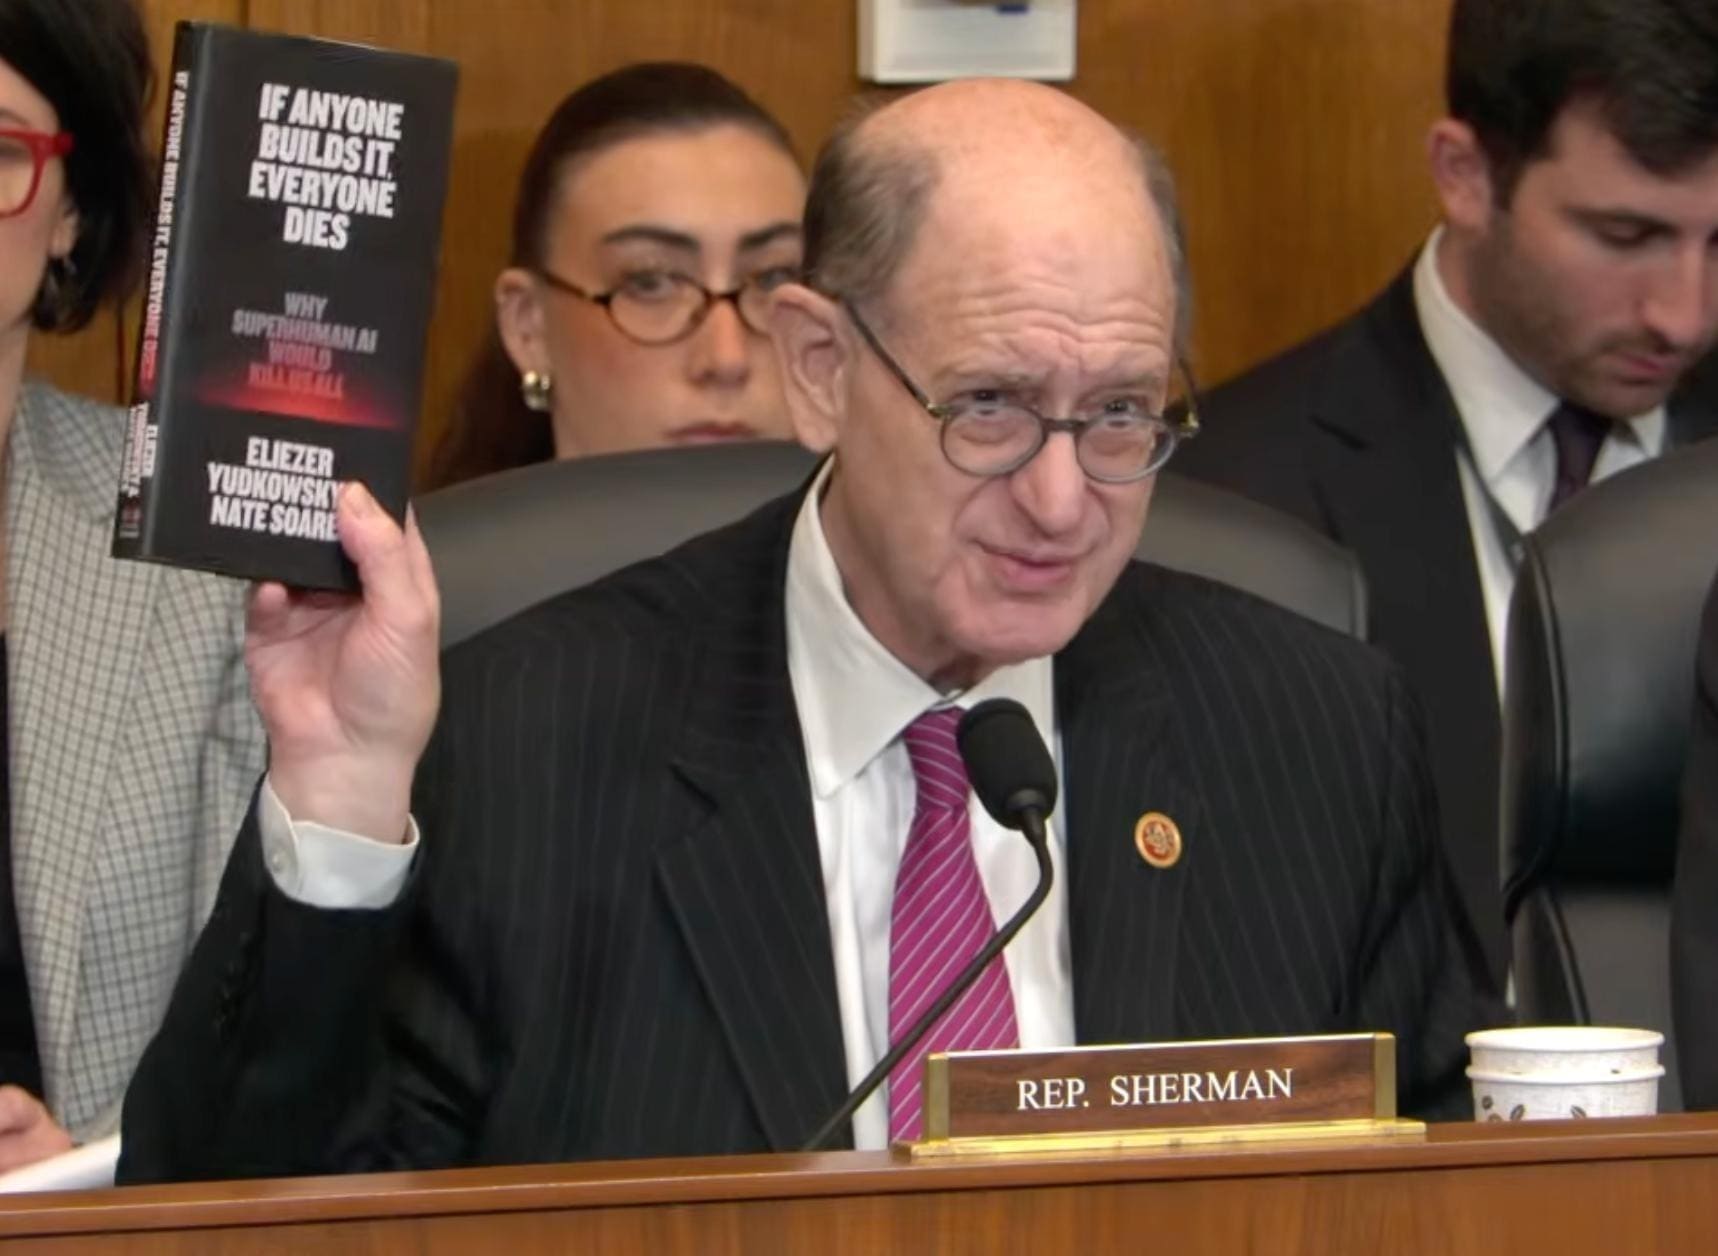
In celebration of still being alive and fighting, we are giving away 1,000 Amazon e-books of “If Anyone Builds It, Everyone Dies”. Feel free to send a copy to yourself, a loved one, or a friend—we need all hands on deck.
Today marks exactly one year since If Anyone Builds It, Everyone Dies: Why Superhuman AI Would Kill Us All, by Eliezer Yudkowsky and Nate Soare...
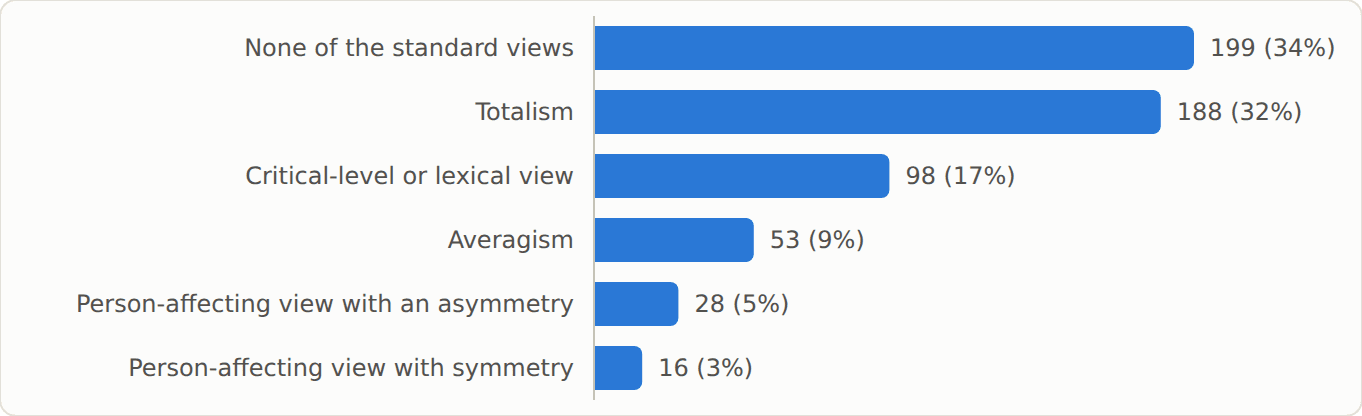
Two weeks ago, I released a population ethics quiz. 582 people took it.[1] Here's what I learned from reading the responses.
Cross-posted from my website.
Preamble, and a new edition of the quiz
I was worried that I'd...

I like this article and I agree with the argument in principle, but I'd like to see a bit more information presented about how the elasticity parameter is estimated.
In other words, what data has been used to compute this parameter? Experiments where people make choices among different lotteries? Implicit choices where people make tradeoffs involving risk? Stated preferences over comparisons of societal distributions of wealth?
I think it is mainly from individuals' explicit preferences over hypothetical gambles for income streams. e.g. if you are indifferent between a sure salary of $50,000 PA and a 50-50 gamble between a salary of $25,000 or one of $100,000, then that fits logarithmic utility (eta = 1). Note that while people's intuitions about such cases are far from perfect (e.g. they will have status quo bias) this methodology is actually very similar to that of QALYs/DALYs. But I imagine all methods you mention are used. Also other methods such as happiness surveys give results in the same ballpark. If asking about ideal societal distribution, then that is actually a somewhat different question as there could be additional moral reasons in favour of equality or priority to the worst off on top of diminishing marginal utility effects. Eta is typically intended to set aside such issues, though there are other tests to measure those.
Thank you Toby. The 'preference over gambles' as a way of measuring diminishing marginal utility will depend strongly on the expected utility maximization assumption; in practice, it could be vulnerable to reference-point effects I believe. (Also the logarithmic utility function is obviously an imposed parametric assumption, but a good start.)
Still, these approaches seem reasonable, especially insofar as broadly similar results come from varying contexts.