Comments
TL;DR: 9-week, full-time AI safety research fellowship in London. Work closely with mentors from leading orgs such as Google DeepMind, Redwood Research, SecureBio, etc. Receive a £6-8k stipend, £2k accommodation + travel support, £2.5k+ compute, co-working (with meals) at LISA. ~70% of recent fellows continued on fully-funded extensions (up to 6 months).
Apply by Sunday, 30 November 2025 (UTC): https://pivotal-research.org/fellowship
What You'll Do
Work with your mentor from Google DeepMind, GovAI, UK AISI, Redwood Research, SecureBio, FAR AI, and other leading organisations to produce AI safety research (in Technical Safety, Governance & Policy, Technical Governance, or AIxBio). Most fellows complete a 10-20 page research paper or report. 70% of recent fellows are doing fully funded extensions for up to 6 months.
Support
We try to provide everything that helps you focus on and succeed with your research:
- Research management alongside mentorship
- £6,000-8,000 stipend (seniority dependent)
- £2,000 accommodation support + travel support
- £2,500+ compute budget
- Co-working at LISA with lunch and dinner provided
More information on our fellowship page
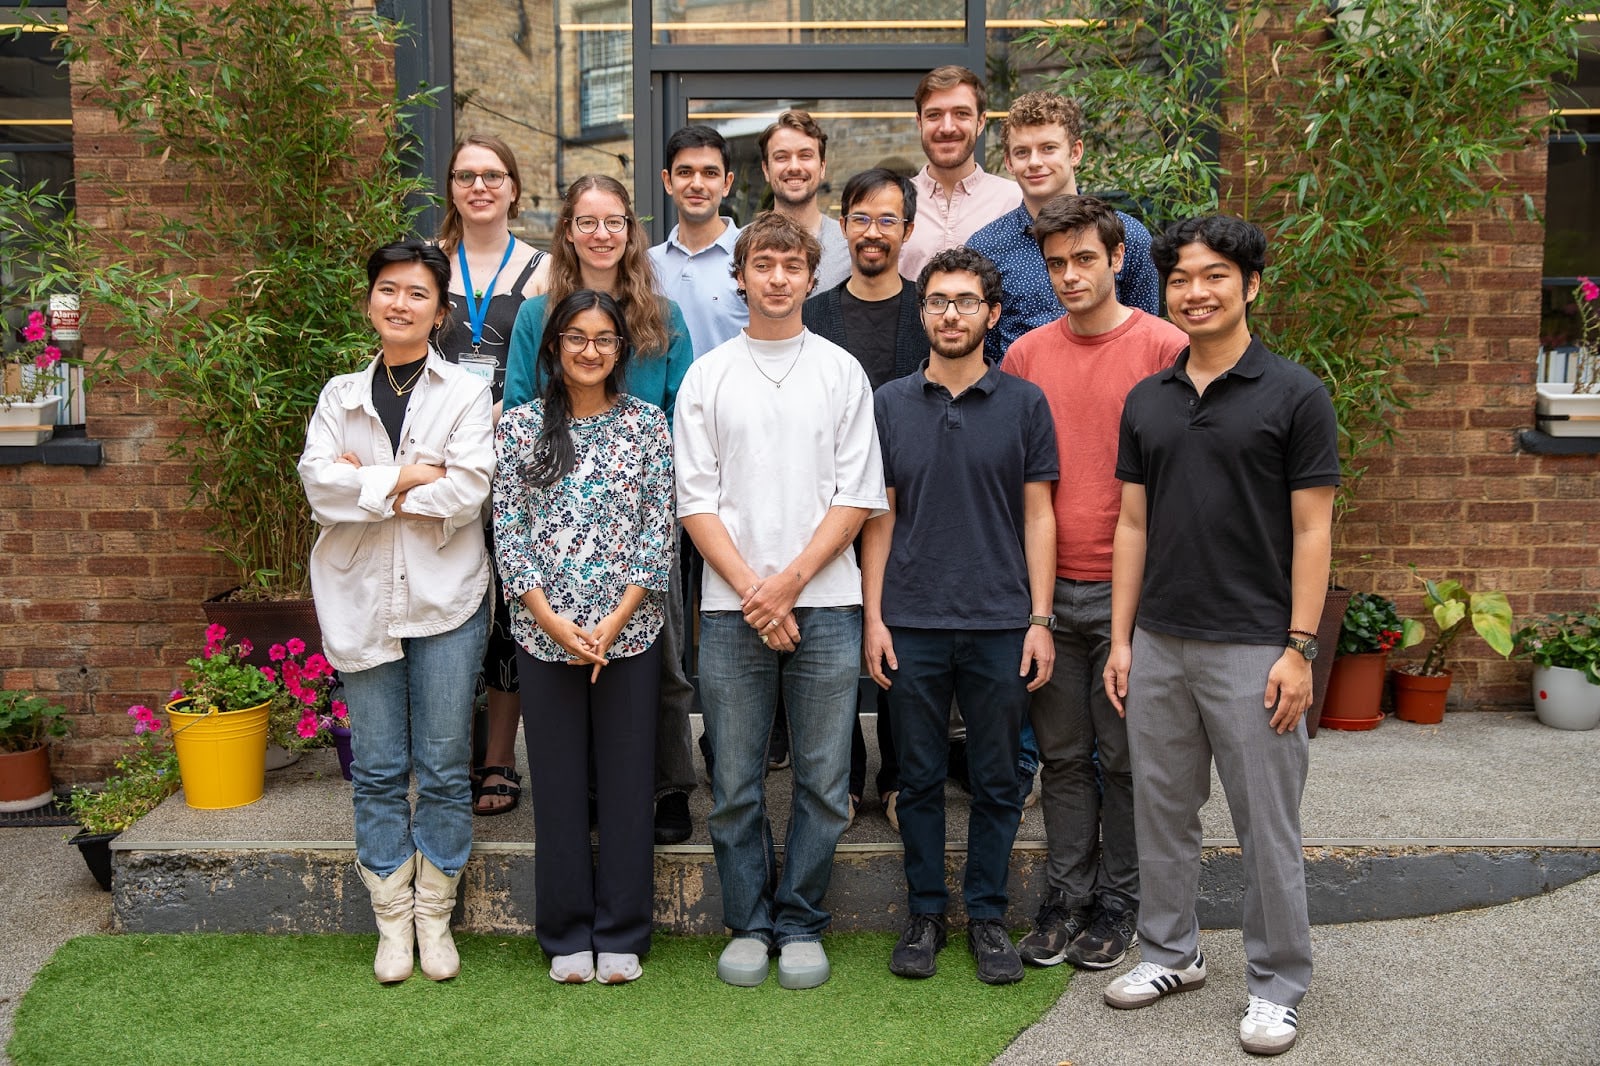
Mentors (more to be added):
- Ben Bucknall (Oxford Martin AIGI): Model Authenticity Guarantees
- Dylan Hadfield-Menell (MIT): Moving beyond the post-training frame for alignment: interpretability, in-context alignment, and institutions
- Edward Kembery (SAIF): International Coordination on AI Risks
- Emmie Hine (SAIF): Chinese AI Governance
- Erich Grunewald (IAPS): Impact & Effectiveness of US Export Controls
- Jesse Hoogland (Timaeus): SLT for AI Safety
- Prof. Robert Trager (Oxford Martin AIGI): Technical Scoping for Global AI Project
- Elliott Thornley (MIT): Constructive Decision Theory
- Lucius Caviola (Leverhulme): Digital Minds in Society
- Jonathan Happel (TamperSec): Hardware-Enabled AI Governance
- Joshua Engels & Bilal Chughtai (GDM): Interpretability
- Julian Stastny (Redwood): Studying Scheming and Alignment
- Lewis Hammond (Cooperative AI): Cooperative AI
- Max Reddel (CFG): Middle-Power Strategies for Transformative AI
- Noah Y. Siegel (GDM): Understanding Explanatory Faithfulness
- Noam Kolt (Hebrew University): Legal Safety Evals
- Oscar Delaney (IAPS): Geopolitical Power and ASI
- Peter Peneder & Jasper Götting (SecureBio): Building next-generation evals for AIxBio
- Stefan Heimersheim (FAR AI): Mechanistic Interpretability
- Tyler Tracy (Redwood): Running control evals on more complicated settings
Who Should Apply
Anyone wanting to dedicate at least 9 weeks to intensive research and excited about making AI safe for everyone. Our fellows share one thing (in our biased opinion): they're all excellent. But otherwise, they vary tremendously – from 18 y.o. CS undergrad to physics PhD to software engineer with 20 years of experience.
Our alumni have gone on to:
- Work at leading organisations like GovAI, UK AISI, Google DeepMind, Timaeus, etc.
- Found AI safety organisations like PRISM Evals and Catalyze Impact
- Continued their research with extended funding
This is our 7th cohort. If you're on the fence about applying, we encourage you to do so. Reading the mentor profiles and application process itself helps clarify research interests, and we've seen fellows from diverse backgrounds produce excellent work.
Deadline: Sun. November 30, 2025 (UTC)
Learn more: https://pivotal-research.org/fellowship
The program is in-person in London, with remote participation only for exceptional circumstances.