Comments
The effect of health insurance on health, such as the old RAND study, the Oregon Medicaid expansion, the India study from a couple years ago, or whatever else is out there.
Robin Hanson likes to cite these studies as showing that more medicine doesn't improve health, but I'm skeptical of the inference from 'not statistically significant' to 'no effect' (I'm in the comments there as "Unnamed"). I would like to see them re-analyzed based on effect size (e.g. a probability distribution or confidence interval for DALY per $).

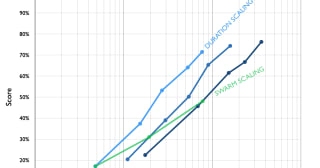

Can we hear about why you want to take another look at Egger et al. (2021)? This is a really important paper and it's important to get this stuff right; OTOH, its data and programs are publicly accessible (download link here), the journal has a pretty robust replication policy...I guess I'm thinking that if something is wrong in this paper it's going to be off in the text and not in the code, i.e. that any mistakes are going to be conceptual. WDYT?
I'd expect this article to be pretty solid, but errors in top journals do happen.
Yep, I recall this case from Bryan Caplan as well: https://betonit.substack.com/p/a-correction-on-housing-regulation
I happen to think Johannes is unusually careful about this stuff; per the original UCT evaluation:
so I assume a similar level of care in Egger et al., on which he is coauthor
It's worth noting that the second of those papers actually has recently been reanalyzed, and Cutler and Miller have now published a response to the reanalysis, as well. I think there is probably more work one could do on this (e.g., updating the difference-in-differences estimators in the original paper to reflect the current methodological state-of-the-art), but I also think it's fair to say that the result has already been subjected to thorough and meaningful scrutiny.