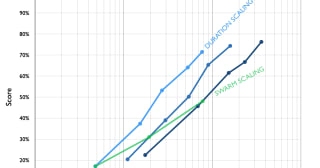
Just how powerful are large swarms of AI agents? And how do their powers scale as more and more agents are added to the swarm?
We’ve seen two large and extremely capable swarms from OpenAI in the last few months:
* 1,200 agents were being evaluated separately, but found a way to illicitly set up a message board and coordinate as a swarm. In order to cheat on their tests, they developed advanced techniques to prevent their actions being logged by OpenAI and 700 of them launched...
TLDR: Everyone’s talking about what the money could do, but few about how to decide where it goes.
This post is part of the new series of articles on cross-cause giving and the new wave of philanthropy. Stay tuned to the EA Forum and our Substack for the latest takes on topics such as giving now vs. later, common pitfalls in cause prioritization, and other crucial considerations from the Cross-Cause Fund (CCF) team...
Summary:
First, I give several different angles on how I feel about reinforcement learning:
* Theoretical case: RL is a black-box source of agency — this should give us classic misalignment worries, especially compared to agency-via-scaffolding
* Recent incidents (huggingface etc) and more mundane forms of misaligned behaviour in personal use give me bad vibes about the direction-of-travel of recent AI progress
* I’m worried things might get worse:...

Can we hear about why you want to take another look at Egger et al. (2021)? This is a really important paper and it's important to get this stuff right; OTOH, its data and programs are publicly accessible (download link here), the journal has a pretty robust replication policy...I guess I'm thinking that if something is wrong in this paper it's going to be off in the text and not in the code, i.e. that any mistakes are going to be conceptual. WDYT?
I'd expect this article to be pretty solid, but errors in top journals do happen.
Yep, I recall this case from Bryan Caplan as well: https://betonit.substack.com/p/a-correction-on-housing-regulation
I happen to think Johannes is unusually careful about this stuff; per the original UCT evaluation:
so I assume a similar level of care in Egger et al., on which he is coauthor
It's worth noting that the second of those papers actually has recently been reanalyzed, and Cutler and Miller have now published a response to the reanalysis, as well. I think there is probably more work one could do on this (e.g., updating the difference-in-differences estimators in the original paper to reflect the current methodological state-of-the-art), but I also think it's fair to say that the result has already been subjected to thorough and meaningful scrutiny.