For those who aren't regular readers of alignmentforum or lesswrong, I’ve been writing a 15-part post series “Intro to Brain-Like-AGI Safety”. And the final post is now posted! 🥳🎉🎊
We know enough neuroscience to say concrete things about what “brain-like AGI” would look like (Posts #1–#9);
In particular, while “brain-like AGI” would be different from any known algorithm, its safety-relevant aspects would have much in common with actor-critic model-based reinforcement learning with a multi-dimensional value function (Posts #6, #8, #9);
“Understanding the brain well enough to make brain-like AGI” is a dramatically easier task than “understanding the brain” full stop—if the former is loosely analogous to knowing how to train a ConvNet, then the latter would be loosely analogous to knowing how to train a ConvNet, and achieving full mechanistic interpretability of the resulting trained model, and understanding every aspect of integrated circuit physics and engineering, etc. Indeed, making brain-like AGI should not be thought of as a far-off sci-fi hypothetical, but rather as an ongoing project which may well reach completion within the next decade or two (Posts #2–#3);
In the absence of a good technical plan for avoiding accidents, researchers experimenting with brain-like AGI algorithms will probably accidentally create out-of-control AGIs, with catastrophic consequences up to and including human extinction (Posts #1, #3, #10, #11);
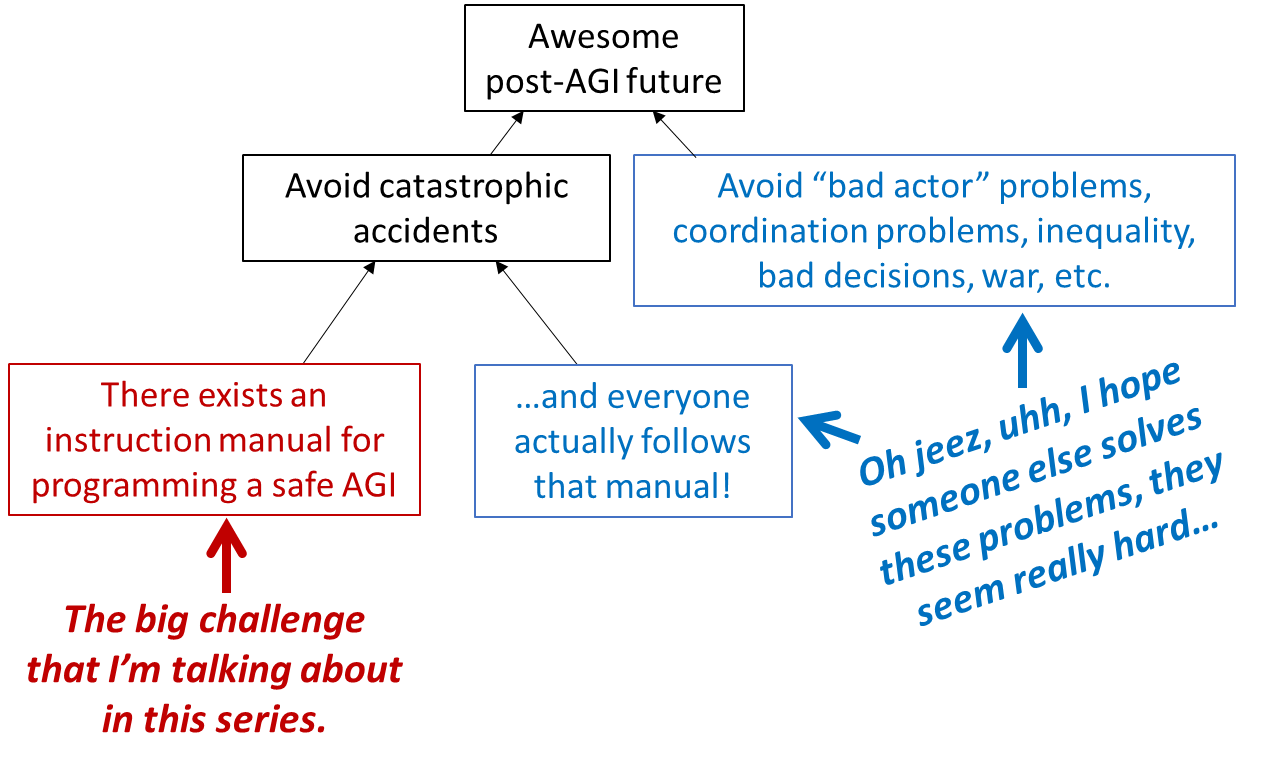
Right now, we don’t have any good technical plan for avoiding out-of-control AGI accidents (Posts #10–#14);
Creating such a plan seems neither to be straightforward, nor to be a necessary step on the path to creating powerful brain-like AGIs—and therefore we shouldn’t assume that such a plan will be created in the future “by default” (Post #3);
There’s a lot of work that we can do right now to help make progress towards such a plan (Posts #12–#15).
General notes
The series has a total length comparable to a 300-page book. But I tried to make to easy to skim and skip around. In particular, every post starts with a summary and table of contents.
The last post lists seven open problems / projects that I think would help with brain-like-AGI safety. I’d be delighted to discuss these more and flesh them out with potential researchers, potential funders, people who think they’re stupid or counterproductive, etc.
General discussion is welcome here, or at the last post, or you can reach out to me by email. :-)
Note: This post was crossposted from the Coefficient Giving Farm Animal Welfare Research Newsletter by the Forum team, with the author's permission. The author may not see or respond to comments on this post.
Subtitle: On vegan advocacy, effective altruism, and FIFA
I turn 40 today. Here are some hot takes.
On factory farming
1. Our biggest challenge is salience. If factory farming led the evening news, it wouldn’t last lo...
On October 22nd starting at 10:00am Pacific Time, Every.org is matching donations to select animal welfare organizations at a 2:1 rate, up to $2,000 per donor per nonprofit (so if you give up to $2,000, they will contribute up to $4,000 and the nonprofit will get up to $6,000). The first donation a donor makes to each eligible nonprofit will be matched, and donors can get the match for multiple $2,000 donations. So, you can get more than $2,000 matched by donating $2,000 one time to multiple...
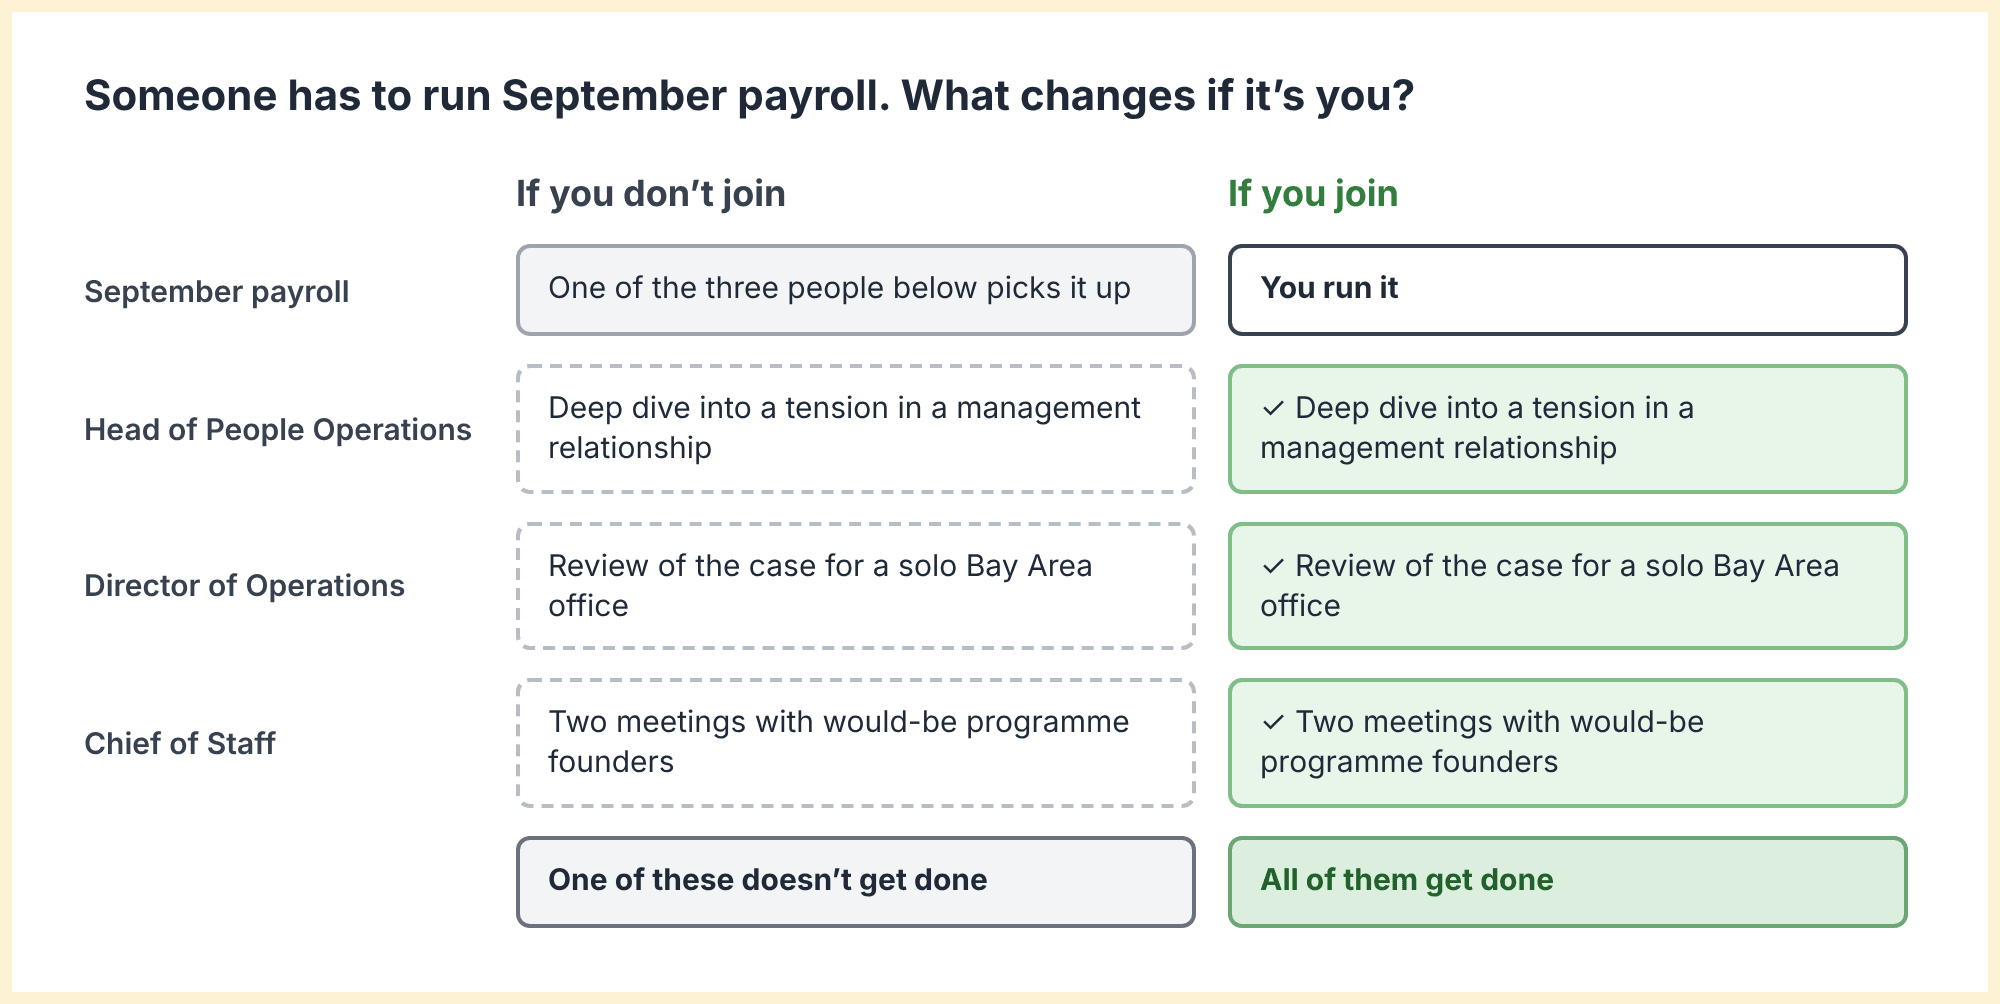
When speaking to candidates who are considering working with us at 80,000 Hours, I often hear people worry about replaceability.
The familiar version of the worry is about whether the organisation will hire someone else in your place. If it will, then the difference you make by taking the job is only the difference between you and them.
There are a couple of well-known answers to that. The person hired in your place probably cares about the world too, and would go on to do somethi...