Comments
More from the author
Curated and popular this week
Note: This post was crossposted from Planned Obsolescence by the Forum team, with the author's permission. The author may not see or respond to comments on this post.
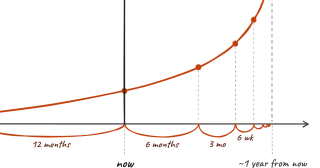
Subtitle: If acceleration compounds, the naive extrapolation implies superintelligence within a year
This post discusses a public METR report on AI R&D acceler...
70
TL;DR:
* When we started Rethink Priorities (RP) in 2018, our mission was, simply put, to close the knowledge gaps that stopped people from improving the world as much as they could. That hasn’t changed much, but the landscape we’re doing it in is shifting.
* In 2027, we plan to grow our core GHD, Animal Welfare, and Worldview Investigations teams to take on emerging priorities across causes, including those that the forthcoming transformative AI is creating.
...
This was cross-posted from the Animal Charity Evaluators blog.
We update our list of recommendations annually. This year, we announced our recommendations on November 10.
Most people who care about animals arrive at the same impas...
Recent opportunities to take action
There is often a clash between "alignment" and "capabilities" with some saying AI labs are pretending to do alignment while doing capabilities and others say they are so closely tied it's impossible to do good alignment research without producing capability gains.
I'm not sure this discussion will be resolved anytime soon. But I think it's often misdirected.
I think often what people are wondering is roughly "is x a good person for doing this research?" Should it count as beneficial EA-flavored research, or is it just you being an employee at a corporate AI lab? The alignment and capabilities discussions often seem secondary to this.
Instead, think we should stick to a different notion: something is "pro-social" (not attached to the term) AI x-risk research if it's research that (1) has a shot of reducing x-risk from AI (rather than increasing it or doing nothing) and (2) is not incentivized enough by factors external to the lab, to pro-social motivation, and to EA (for example: the market, the government, the public, social status in silicon valley, etc.)
Note (1) should include risks that the intervention changes timelines in some negative way, and (2) does not mean the intervention isn't incentivized at all, just that it isn't incentivized enough.
This is actually similar enough to the scale/tractability/neglectedness framework but it (1) incorporates downside risk and (2) doesn't run into the problem of having EAs want to do things "nobody else is doing" (including other EAs). EAs should simply do things that are underincentivized and good.
So, instead of asking things like, "is OpenAI's alignment research real alignment?" ask "how likely is it to reduce x-risk?" and "is it incentivized enough by external factors?" That should be how we assess whether to praise the people there or tell people they should go work there.
Thoughts?
Note: edited "external to EA" to "external to pro-social motivation and to EA"