Claim: Credible plans for a "pivotal act" may drive AI race dynamics
(Epistemic status: I had mathematica do all the grunt work and did not check the results carefully)
Consider a simple normal-form game with two equally capable agents A and B, each of which is deciding whether to aggressively pursue AI development, and three free parameters:
the probability pdoom that accelerating AI development results in an existential catastrophe (with utility -1 for both agents, versus a utility 0 status quo).
the utility u1 of developing the first friendly AI
the utility −1<u2<u1 of the other agent developing friendly AI
We'll first assume the coin only gets flipped once: developing a friendly AI lets you immediately control all other AI development.
Since our choice of parameterization was in retrospect one that requires a lot of typing, we'll define u+=u1+u22, u−=u1−u+=u+−u2 and then rescale to get something more readable
Note: This post was crossposted from Planned Obsolescence by the Forum team, with the author's permission. The author may not see or respond to comments on this post.
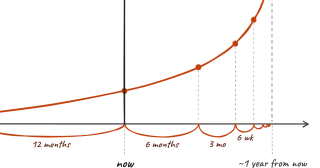
Subtitle: If acceleration compounds, the naive extrapolation implies superintelligence within a year
This post discusses a public METR report on AI R&D acceler...
TL;DR:
* When we started Rethink Priorities (RP) in 2018, our mission was, simply put, to close the knowledge gaps that stopped people from improving the world as much as they could. That hasn’t changed much, but the landscape we’re doing it in is shifting.
* In 2027, we plan to grow our core GHD, Animal Welfare, and Worldview Investigations teams to take on emerging priorities across causes, including those that the forthcoming transformative AI is creating.
...
This was cross-posted from the Animal Charity Evaluators blog.
We update our list of recommendations annually. This year, we announced our recommendations on November 10.
Most people who care about animals arrive at the same impas...
Claim: Credible plans for a "pivotal act" may drive AI race dynamics
(Epistemic status: I had mathematica do all the grunt work and did not check the results carefully)
Consider a simple normal-form game with two equally capable agents A and B, each of which is deciding whether to aggressively pursue AI development, and three free parameters:
We'll first assume the coin only gets flipped once: developing a friendly AI lets you immediately control all other AI development.
Since our choice of parameterization was in retrospect one that requires a lot of typing, we'll define u+=u1+u22, u−=u1−u+=u+−u2 and then rescale to get something more readable
AccelerateDon'tAccelerateu+u+−u−,u++u−Don'tu++u−,u+−u−pdoom1−pdoom
Now consider the case where (Accelerate, Accelerate) instead flips two coins.
AccelerateDon'tAccelerateu+(1−pdoom)−pdoomu+−u−,u++u−Don'tu++u−,u+−u−pdoom1−pdoom
This is potentially a much safer situation: