I used an LLM to help draft this post, but I’ve edited/rewritten it extensively and endorse it.
AI in Context is a channel about transformative AI and its risks, published by 80,000 Hours.
Writing up our current approach to thumbnails, which is nowhere near perfect, for easy shareability and cross-pollination of lessons. Would love to hear what other people are trying!
Making thumbnails
We're lucky enough to have folks at 80k with great design instincts. We work with them as well as with some external folks, but finding great people is harder than we expected. Let us know if this is something you or someone you know would be great at!
We iterate way more than people expect
Every video gets ~dozens of thumbnail variations, most of which are made after launch. You can see the full set of data on our IABIED thumbnails here.
I believe 2/3 of our winning thumbnails (maybe all 3) were made after launch. It's pretty hard to predict ahead of time which thumbnails will do well.
We launch with a few thumbnails we're excited about, a/b/c testing them
We tried pre-launch testing via paid ads once, didn't correlate well, but we haven't tried super intensely
We iterate from there. If one is doing well, or the video is doing well, we do new ones similar to what we've tried. If the views are lower or nothing is breaking out, we try more variance. This could be from thumbnails we had ready, or new ones we make with the new information. We also swap out titles, usually not at the same time so we get the full information.
We have someone checking ~continuously through the first few days.
Tests run for about six hours. For our view rate, tests stabilize around six hours. If you check at three hours and again at six, the numbers often shift meaningfully. After six, they tend to settle.
YouTube's AB testing data updates roughly every 30 minutes, not in real time. You'll see the same numbers for a while and then a sudden jump.
We have a Slack thread for every video where we dump every thumbnail iteration and every test result. It's kind of unhinged and there's probably a better way to do it.
If one thumbnail is clearly tanking, we'll cut the test early rather than wait for statistical significance
When views are low and the test is running but not informative, sometimes the right move is to stop testing entirely for a while and just let the winning thumbnail run since the algorithm is sometimes looking for your audience.
What we've learned
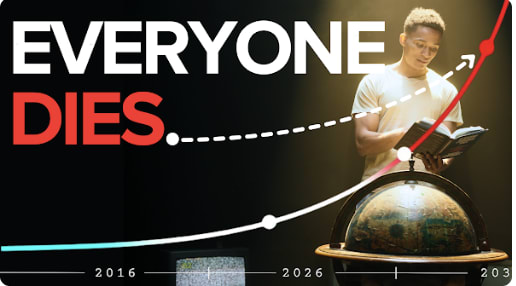
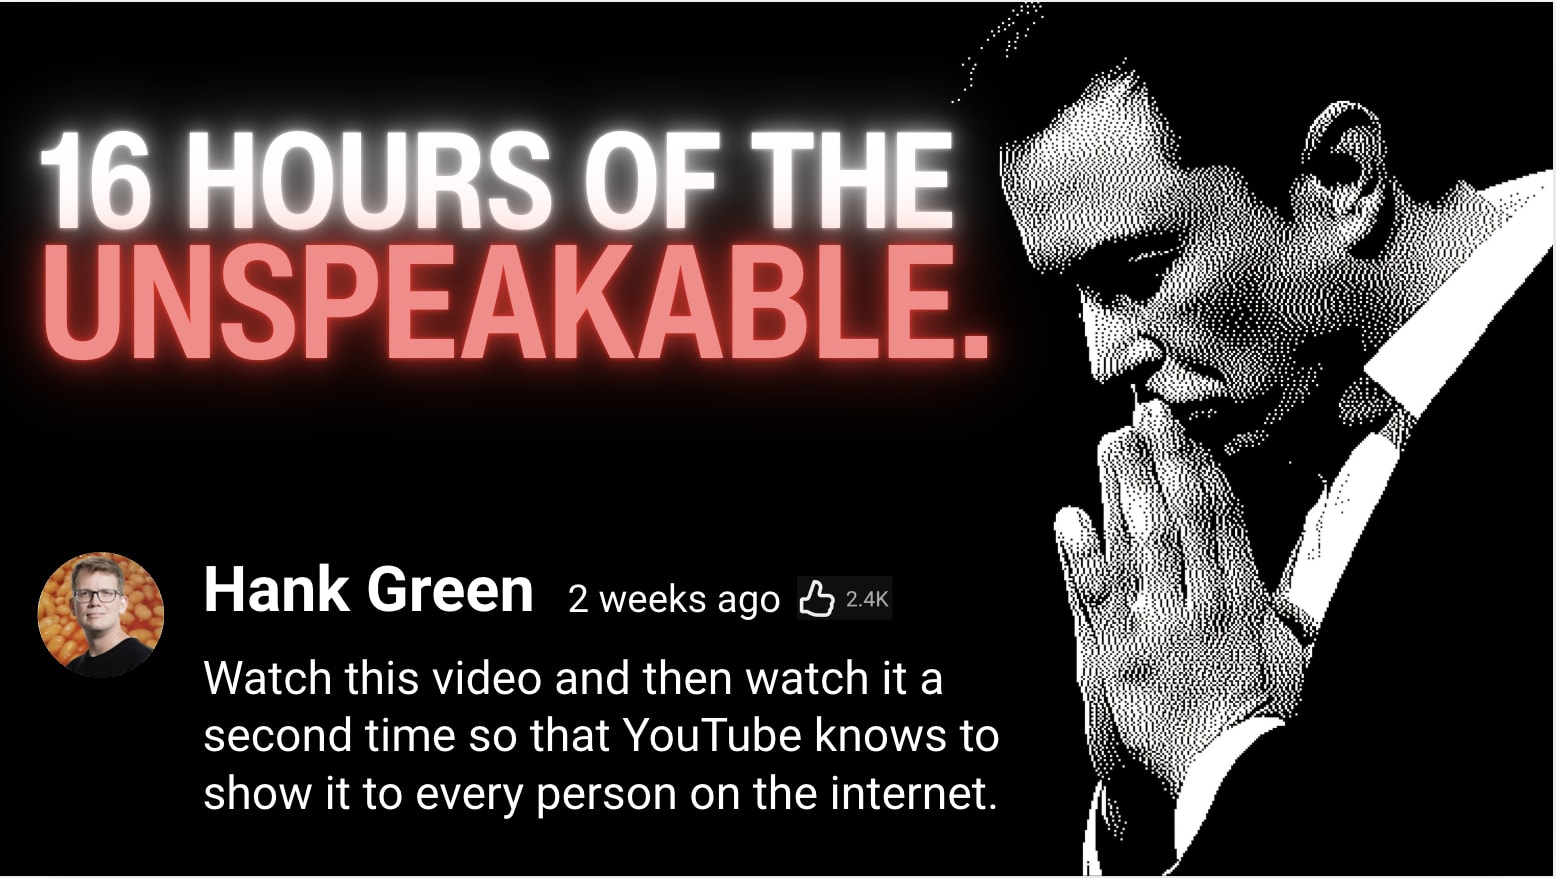
Big text is good
Graphs are surprisingly strong
Host face helps, but not always
e.g. this is our winning MechaHitler thumbnail
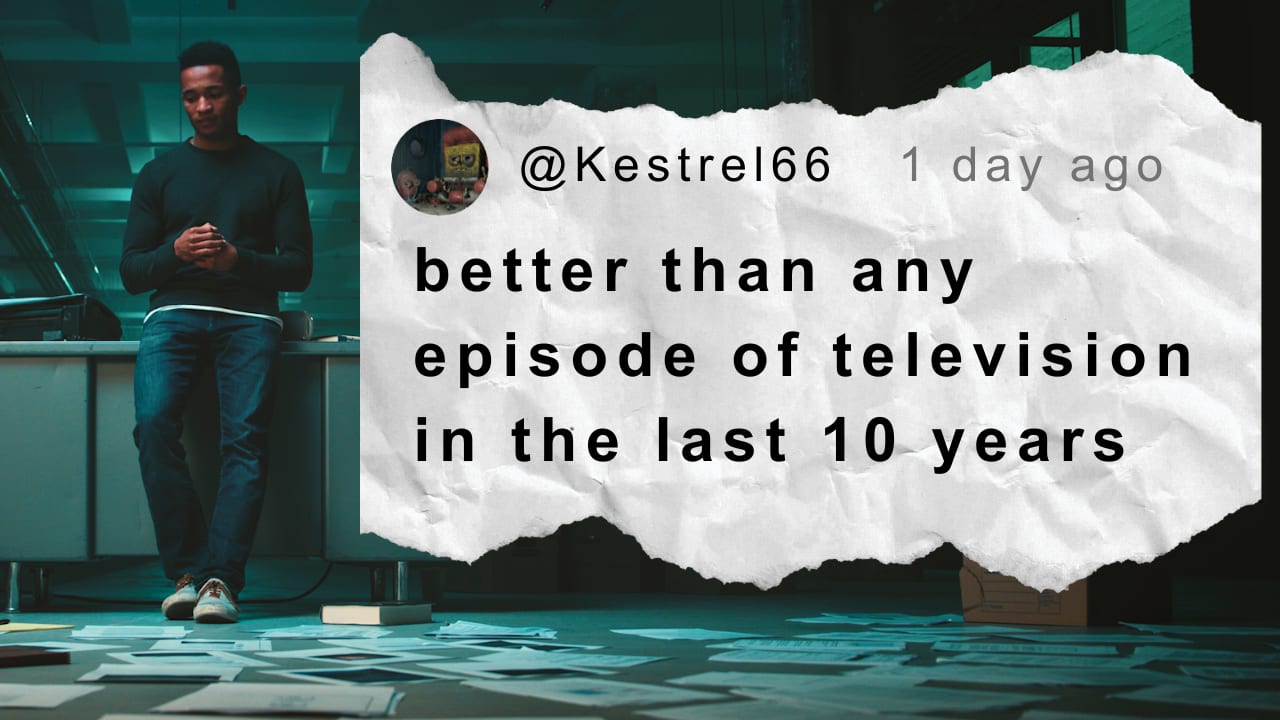
Having a "glowing" comment in the thumbnail (that is, grabbing a really positive comment on the video and putting it in the thumbnail) sometimes works but not always. Veritasium and 3B1B do this. We have a theory that it needs to be really specific.
Headline finding: I audited 17 AI Safety Talent programmes. Zero of 17 have published any comparison group, rejected-applicant follow-up, matched control or randomisation. Not one. Every programme that mentions a counterfactual does it by asking participants to self-report.
Background
At least $70 million...
In celebration of still being alive and fighting, we are giving away 1,000 Amazon e-books of “If Anyone Builds It, Everyone Dies”. Feel free to send a copy to yourself, a loved one, or a friend—we need all hands on deck.
Today marks exactly one year since If Anyone Builds It, Everyone Dies: Why Superhuman AI Would Kill Us All, by Eliezer Yudkowsky and Nate Soare...
A year ago I posted that YCombinator (YC) companies didn’t seem to be growing faster since the release of ChatGPT in 2022. I reran that experiment and found that 2023+ YC companies are arguably growing a bit faster than pre-2023 companies (including AfterQuery, ...